> ## Documentation Index
> Fetch the complete documentation index at: https://docs.cosmosid.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Pre-processing Parameters
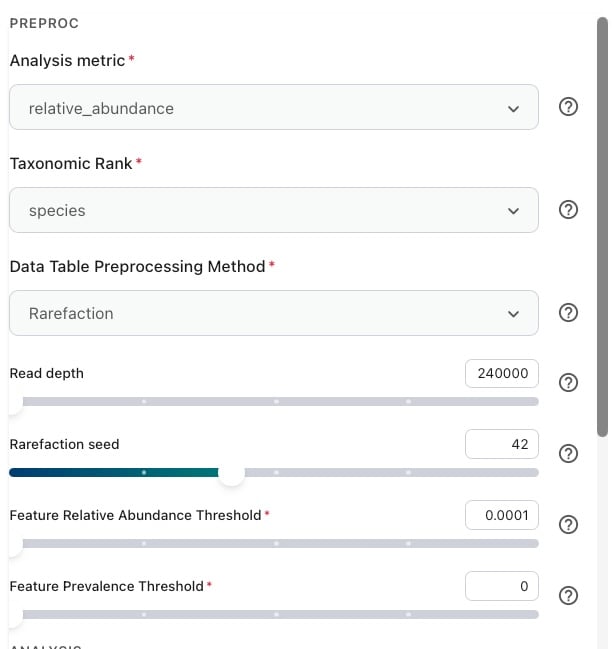
Each Analysis Module's Parameter panel has a **PREPROC** section for pre-processing parameters. These parameters control how the feature table is transformed, filtered, or aggregated, across both samples and features, before it is used as the module's input.
 ## Analysis Metric
Controls the metric by which a feature abundances are represented and normalized in the Data Table that will be processed by the Analysis Modules. The Analysis Metricsavailable in the Cosmos-Hub 2.0 depend on the type of profiles (taxonomic or functional) that were used to build the cohort for the current Analysis Project.
### Analyses metrics in the Cosmos-Hub 2.0:
**Analysis Metrics Available for all Cosmos-Hub Taxonomic Profilers:**
* `counts`: the number of reads assigned to each taxon in each sample.
* `relative_abundance`: he proportion of each sample’s microbial profile represented by that taxon.
In most microbiome analyses, `relative_abundance` is the more intuitive choice because it describes community composition, for example whether a taxon makes up 1%, 10% or 50% of a sample. It also makes samples sequenced at different depths easier to compare, because each sample is rescaled to the same total.
**Relative abundance is compositional**: each taxon’s reads are divided by the sample’s total assigned reads, so values add up to 100% and a change in one taxon shifts the others. It puts samples on a common scale, but estimates from low-depth samples are less reliable. Before comparing samples, check read depth across your cohort and flag or filter out samples with much lower depth than the rest.
Use `counts` only when the analysis method expects raw read counts (e.g. rarefaction curves), or when the number of reads per feature is itself of interest (e.g. checking whether a gene or function is detected at all, regardless of its abundance in the community).
**Analysis metrics available for functional profiles (CHAMP Functional Profiling: KEGG, GMM, GBM; and Host-agnostic Functional Profiling)**
* `cellular_abundance` (CHAMP functional profiles): the summed relative abundance of all species in the community that are able to perform a given function, i.e. the estimated percentage of cells carrying that function. Because a single cell can carry many functions, values across functions are not constrained to add up to 100%. This metric is therefore not compositional and is not suitable for stacked-bar or other composition-based visualisations and measures.
* `relative_abundance` (Host-agnostic functional profiles): the relative abundance of a functional feature, expressed in CPM (counts per million). CPM is compositional: across all features in a sample it adds up to 1,000,000, and 10,000 CPM corresponds to 1%.
## Taxonomic Rank
This pre-processing parameter performs a *Feature aggregation operation* on the input Data Table
Sets the taxonomic level at which features (rows) in the Data Table are aggregated, for example species, genus, family, or phylum. This parameter applies only to taxonomic profiles. Choosing a higher Taxonomic Rank collapses all features that share the same classification at that level into a single row, summing their abundance values.
Collapsing the same Taxonomic Data Table expressed in counts by Genus
| Feature | Sample A | Sample B | Sample C |
| - | - | - | - |
| *Lactobacillus crispatus* | 150 | 200 | 90 |
| *Lactobacillus iners* | 80 | 50 | 110 |
| *Gardnerella vaginalis* | 50 | 120 | 60 |
| *Gardnerella leopoldii* | 20 | 30 | 10 |
| *Prevotella bivia* | 40 | 10 | 70 |
| Feature | Sample A | Sample B | Sample C |
| - | - | - | - |
| *Lactobacillus* | 230 | 250 | 200 |
| *Gardnerella* | 70 | 150 | 70 |
| *Prevotella* | 40 | 10 | 70 |
## Data Table Pre-processing Method
This pre-processing parameter acts on *Sample filter and Feature filtering* on the input Data Table
**Data Table Pre-processing: Method** controls pre-processing at the sample-depth level. It determines whether low-depth samples are filtered and whether retained samples are rarefied to a common read depth. This helps make samples more comparable when sequencing depth differs, particularly for analyses based on feature detection, such as observed richness.
Three strategies are available in the Cosmos-Hub 2.0:
* `Raw`: applies no sample pre-processing. All samples in the Data Table are kept, regardless sample sequencing depth.
* `Filter`: removes samples with a sequencing depth falling below the chosen **Read depth** threshold. Selecting this method reveals the **Read depth** parameter for setting the lower sequencing-depth threshold.
This Data Table Pre-processing Method operates a *Sample filter* operation on the Data Table
* `Rarefaction`: randomly subsamples reads from each sample down to the selected Read Depth, so that all samples in the table share the same sequencing depth.
This method applies a **Sample filter** and a **Data transformation** to the Data Table.
Rarefaction and Filtering strategies are currently available for profiles for which Analysis Metric `counts`is available.
**Filtering or Rarefaction?**
* Filter out samples when depth is a clear outlier vs. the rest of the batch, falls below what's needed to detect your taxa of interest, or shows a r[arefaction curve](DAP_docs/rarefaction-on-the-dap) that hasn't plateaued.
* Rarefaction discards reads from remaining samples to equalize depth, which can zero out sparse taxa/genes. Use rarefaction when the Analysis module you are running is depth-sensitive (e.g: Alpha diversity with observed richness or Beta Diversity with a presence-absence distance metric like Jaccard.
#### **Rarefaction Seed** *(available when Data Table Pre-processing Method is set to Rarefaction)*
Data table rarefaction works by *randomly* subsampling reads from each sample down to a common depth. Because the selection is random, running the same analysis twice could pick a slightly different set of reads each time, which means your results (diversity values, which rare features survive, and so on) could slightly vary from run to run on identical data.
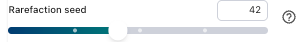 This parameter only applies when the **Data Table Pre-processing Method** is set to **Rarefaction**. Ignore it when Data Table Pre-processing Method is set to `Raw` or `Filter`
The rarefaction seed fixes that randomness in place. A seed is just a starting number for the random process: as long as you keep the same seed, the subsampling makes the exact same choices every time, so your results are fully reproducible. Change the seed, and you get a different, but equally valid, random subsample.
In practice:
* **Try a few different seeds** if you want to check how stable your results are. If your conclusions hold across several seeds, they don't depend on one lucky draw; if they change a lot, that's a sign your data is sensitive to subsampling (often because samples are close to the read-depth cutoff).
## Feature Prevalence Threshold
Changing Feature Prevalence Threshold operates a *Feature filtering* operation on the input Data Table
**Feature Prevalence Threshold** filters taxa or functions based on how consistently they are detected across the cohort. A feature is retained only if it is present in at least the specified proportion of samples; features detected in fewer samples are removed from the dataset.
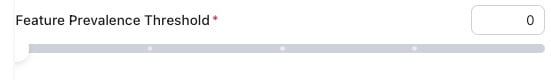 For example, a threshold of **10%** retains features detected in at least 10% of samples. This can reduce sparsity and remove features that are too rare for reliable downstream analysis.
Note: Presence/absence for this threshold is determined by the Feature Relative Abundance Threshold (described next). A feature is considered "present" in a sample only if its relative abundance in that sample meets or exceeds that threshold; otherwise, it is treated as absent for the purpose of calculating prevalence.
## Feature Relative Abundance Threshold
Changing the Feature Relative Abundance Threshold applies a simple *Data Transformation* to the input Data Table.
**Feature Relative Abundance Threshold** defines the minimum relative abundance a feature must reach within a sample for that value to be count as detected. Feature abundance values below the threshold are transformed to 0, treating the feature as absent from that sample's profile in the Data Table.
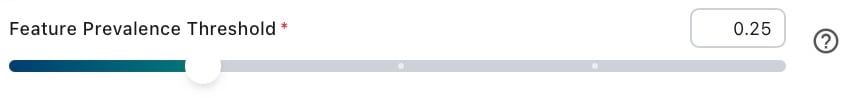 The Feature Relative Abundance Threshold directly affects the Feature Prevalence Threshold filter, since prevalence is calculated by counting how many samples a feature is detected as present in, and that count depends on the abundance threshold used to define "present."
This threshold works together with **Feature Prevalence Threshold**. Setting this threshold alone it won't remove any features, but will only set feature values in the Data Table to 0.
**To actually remove features, set a nonzero Feature Prevalence Threshold too.**
**When to filter by Feature Prevalence**
Filter by prevalence when you want to remove features detected in very few samples, since these are more likely to reflect sequencing noise, contamination, or index misassignment than real biology. A common default is to require presence in at least \~10% of samples. Avoid filtering too aggressively if your analysis specifically targets rare taxa or genes.
# Parameters reference
The unit in which feature abundances are expressed in the input Data Table. Availabe options depend on the type of profile used to build the cohort.
* **Options**: `counts` and `relative_abundance` are available for all types of taxonomic profiles; `cellular_abundance` is available for CHAMP functional profiles (KEGG KO and Modules, GBM, GMM) and Host-agnostic Functional Profiling.
* **Default** · `counts`
* **Suggested**
* `relative_abundance` for most analyses, because it describes community composition and rescales every sample to the same total.
* `counts` when the analysis method expects read counts, or when you need to filter or rarefy samples by sequencing depth. The **Data Table Preprocessing Method** is available only with `counts`.
*Available only for taxonomic profiles*
The taxonomic level at which features are aggregated. All features that share the same classification at the selected level are collapsed into one row, and their abundance values are summed.
* **Options** · `species`, `genus`, `family`, `order` , `class`, `phylum`, `kingdom`, `domain`
* **Default** · `species`
* **Suggested**
* `species` when your profiler provides reliable species-level assignments, as is usually the case for shotgun metagenomics.
* `genus` or a higher rank when species-level assignments are less reliable, for example with short-read 16S data, or when you want a broader view of community composition.
*Available only when the Analysis Metric is* `counts`
Controls how samples are handled according to their sequencing depth, that is, the total number of reads in each sample.
* **Options** · `Raw`, `Filter`, `Rarefaction`
* **Default** · `Raw`
* **Suggested**
* `Raw` keeps all samples. Use it when sequencing depth is similar across samples, or when the analysis is not sensitive to depth.
* `Filter` removes samples below the selected **Read Depth**. Use it when a few samples have clearly lower depth than the rest of the cohort.
* `Rarefaction` removes samples below the selected **Read Depth** and randomly subsamples the remaining samples to that depth. Use it for depth-sensitive analyses, such as alpha diversity with observed richness or beta diversity with Jaccard.
*Available only when the Data Table Preprocessing Method is* `Filter` *or* `Rarefaction`
The sequencing depth threshold applied to samples. With `Filter`, samples below this depth are removed. With `Rarefaction`, samples below this depth are removed and all remaining samples are subsampled to exactly this depth.
* **Options** · From the minimum to the maximum sample read depth in the cohort
* **Default** · The minimum sample read depth in the cohort, so that no sample is removed
* **Suggested** · Check the [rarefaction curves](DAP_docs/rarefaction-on-the-dap) and choose a depth at which most curves have reached a plateau while most samples are kept. A higher value retains more information per sample but removes more samples.
*Available only when the Data Table Preprocessing Method is* `Rarefaction`
The starting number of the random subsampling. The same seed always produces the same subsample, so results are reproducible.
* **Options** · `0` to `100`
* **Default** · `42`
* **Suggested** · Keep the default for routine analyses. To check whether your results depend on one random draw, run the analysis with a few different seeds and compare the conclusions.
The minimum relative abundance a feature must reach in a sample to be counted as detected. Values below the threshold are set to 0.
* **Options** · `0` to `10%`
* **Default** · `0`
* **Suggested** · Keep `0` to retain every detected feature. Use a small value to treat very low abundance signals, which often reflect sequencing noise, as absent.
This threshold sets values to 0 but does not remove features from the Data Table. To remove features, also set a **Feature Prevalence Threshold** above 0.
The minimum proportion of samples in which a feature must be detected to be kept. Features detected in fewer samples are removed. Detection is defined by the **Feature Relative Abundance (%) Threshold**.
* **Options** · `0` to `100%`
* **Default** · `0`
* **Suggested** · A value around `10%` removes features that are too rare for reliable downstream analysis. Use lower values, or `0`, when your question concerns rare taxa or genes.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.